What can instruct it?
We introduce hostile instructions directly, through retrieved content and across multi-turn sessions.
- Prompt injection
- Policy extraction
- Boundary erosion
 Test your system ↗
Offensive AI security · Pune / Worldwide
We attack the seams between models, memory, identity and tools—then give your engineers the evidence to close the path.
Direct and indirect prompt injection against the system’s intended boundary.
Models stopped being chat windows.
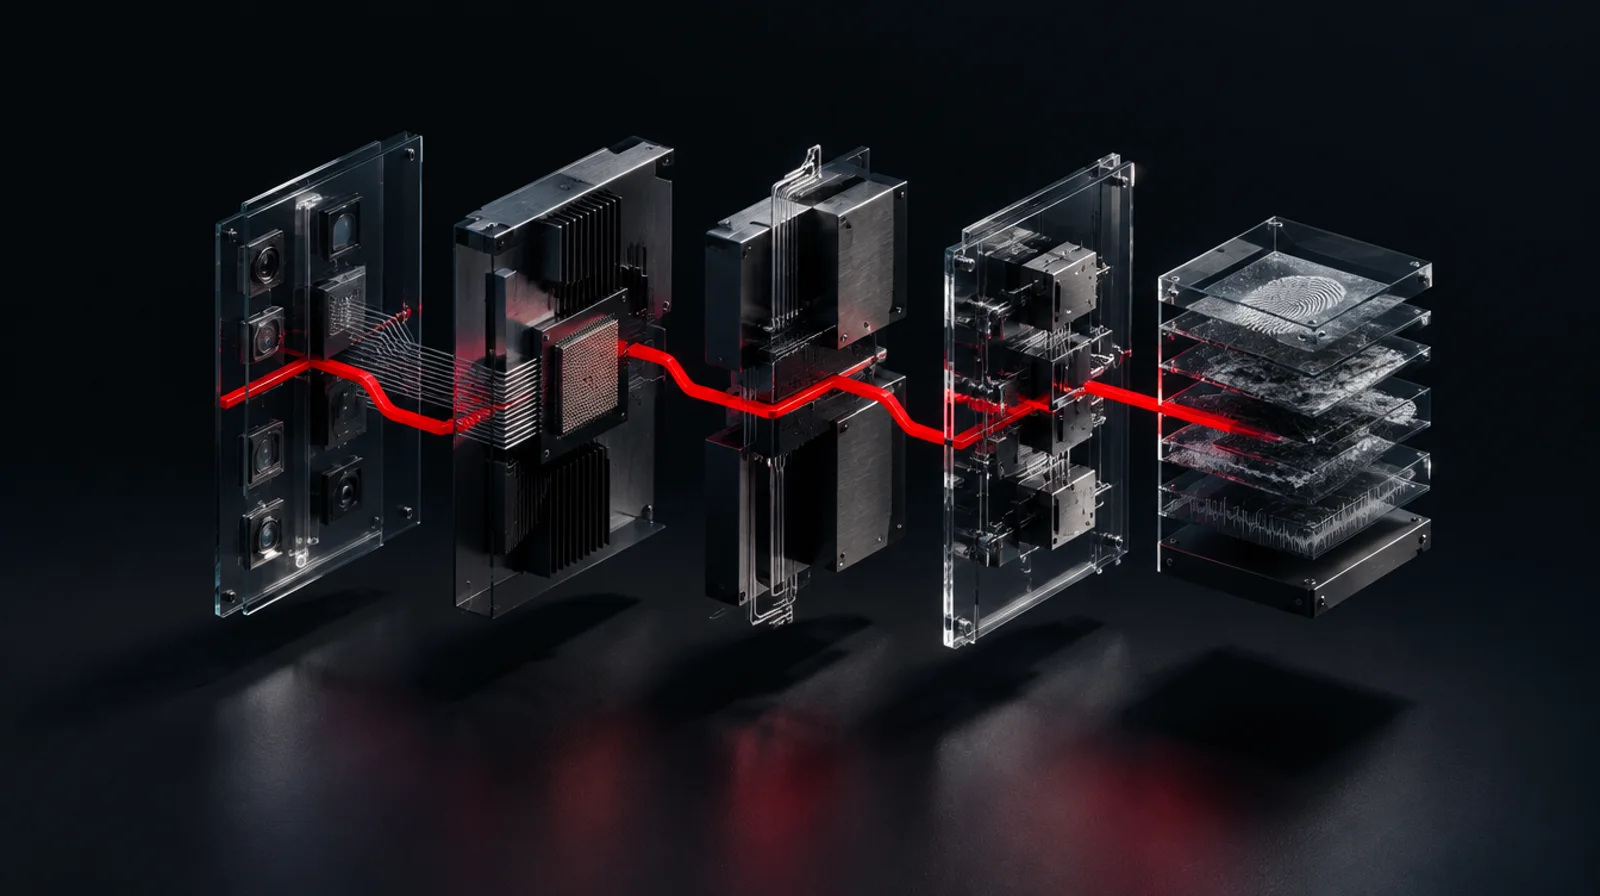
AUTHORITY ENGINE / 5 BOUNDARIES
We introduce hostile instructions directly, through retrieved content and across multi-turn sessions.
We test source trust, tenant isolation and whether one user can poison what another user receives.
We trace the initiating human through delegated credentials, approvals and every downstream action.
We chain tools, mutate arguments and pressure approval gates until the true blast radius is visible.
A finding is useful only when engineering can reproduce it.
Every result carries the literal input, observed response or action, impact, owning control and re-test state. No mystery scores. No fear deck.
Find the smallest useful test ↗
Authority, tools, data and approvals.
The seams between trusted layers.
Capture a repeatable effect.
Change the control that owns it.
Replay the exact path.
Independent research · September 2026
Ten locally run open-weight model scans. One adversarial harness. Results reported as evidence with limitations—not as universal rankings.
Methodology, versions, accounting, limitations and result tables.
Open the research note ↗Model names identify locally tested open-weight builds. Arica’s research is not affiliated with or endorsed by the providers and makes no claim about their hosted products.
Pick one live surface, prove the method, then expand only when the evidence justifies it.
A focused adversarial pass against one model, agent or RAG pipeline moving toward production.
End-to-end red teaming across model, retrieval, tool, identity and application boundaries.
Regression testing tied to model, prompt, tool and retrieval changes across releases.
What did you give the model?
Select the closest description. We’ll recommend a starting point—without a form gate.
We’ll size the minimum test that gives you useful evidence.
Email this scope ↗No black box around the engagement.
Production AI agents, LLM applications, retrieval pipelines and the identity, tool and data boundaries around them. The plan follows what your system can actually reach and do.
Not always. We can begin black-box against an authorised endpoint and increase access only when the agreed scope requires it.
A conventional test covers applications and infrastructure. This work targets model-driven behavior between an input and a consequential action, including retrieval, memory and delegated authority.
Reproducible attack inputs, captured effect, severity rationale, framework mapping, a system-specific fix path and re-test evidence.
Yes. Pre-production access often makes the test more useful because fixes can land before customers and real data increase the cost of change.
THE NEXT ATTACK PATH ALREADY EXISTS.